Multiomics Integration: Methods and Caveats
Abstract
Integrating genomics, transcriptomics, and proteomics promises a fuller picture of biology, but that’s where the hard part starts. This talk surveys the major integration approaches (fusion methods, matrix factorization, deep learning) and the pitfalls that trip people up: batch effects, mismatched scales, missing modalities, and patterns that look real but aren’t. You’ll leave knowing what multiomics integration can deliver, where it breaks down, and how to tell the difference.
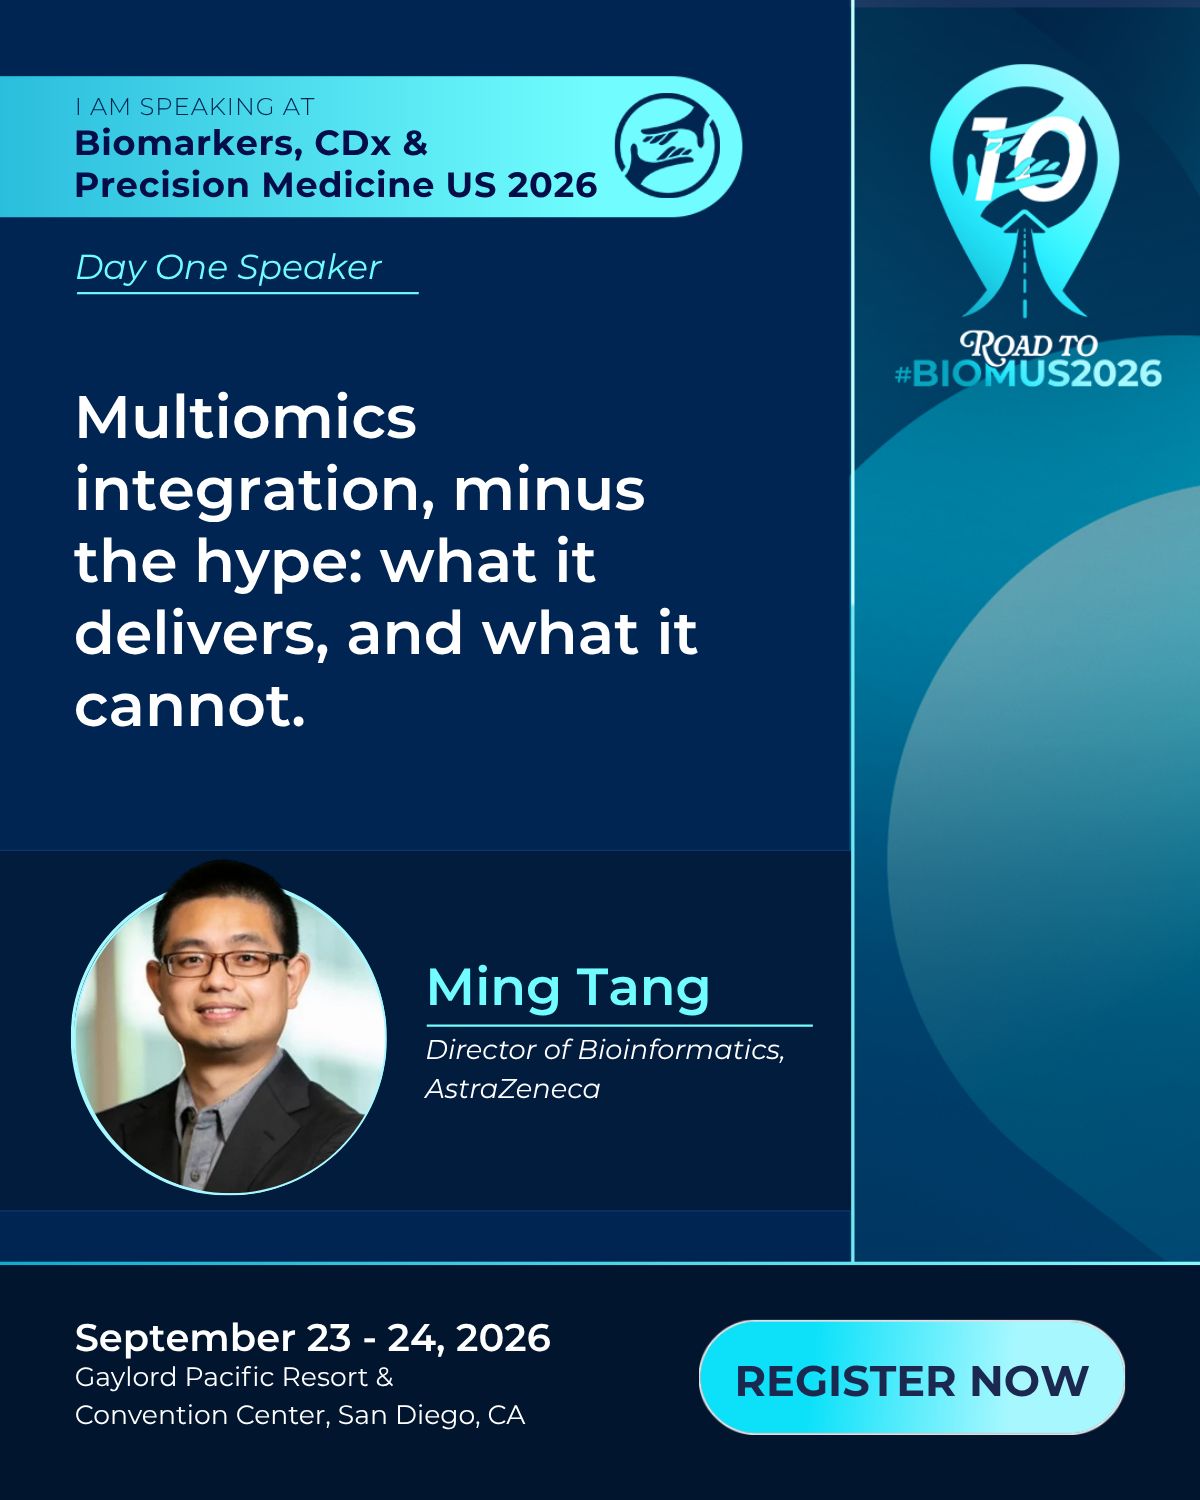
Industry presentation in the Multi-Omics, Spatial & Data programme at Oxford Global’s Biomarkers, CDx & Precision Medicine US 2026 in San Diego. The talk covers what the major multiomics integration methods (fusion approaches, matrix factorization, deep learning) actually deliver, and the pitfalls that trip people up: batch effects, mismatched scales, missing modalities, and patterns that look real but aren’t.
I gave an earlier version of this talk for the SAPA Data Science Community in June 2026. For a hands-on walkthrough of one of these methods, see my post on multi-omics integration with MOFA2.